
Haiku 5.5: The $0.10 Model With a 5x Cliff
Published:
Prices below are a list-price snapshot checked on Oct 8, 2026, and are subject to change.
Start with the credit. This is not a discount on the same model.
The jump is real
Anthropic launched Claude Haiku 5.5 on October 7, 2026, as claude-haiku-5-5, on the Claude Platform, AWS, Google Cloud, and Microsoft Azure / Foundry. Anthropic-reported benchmarks:
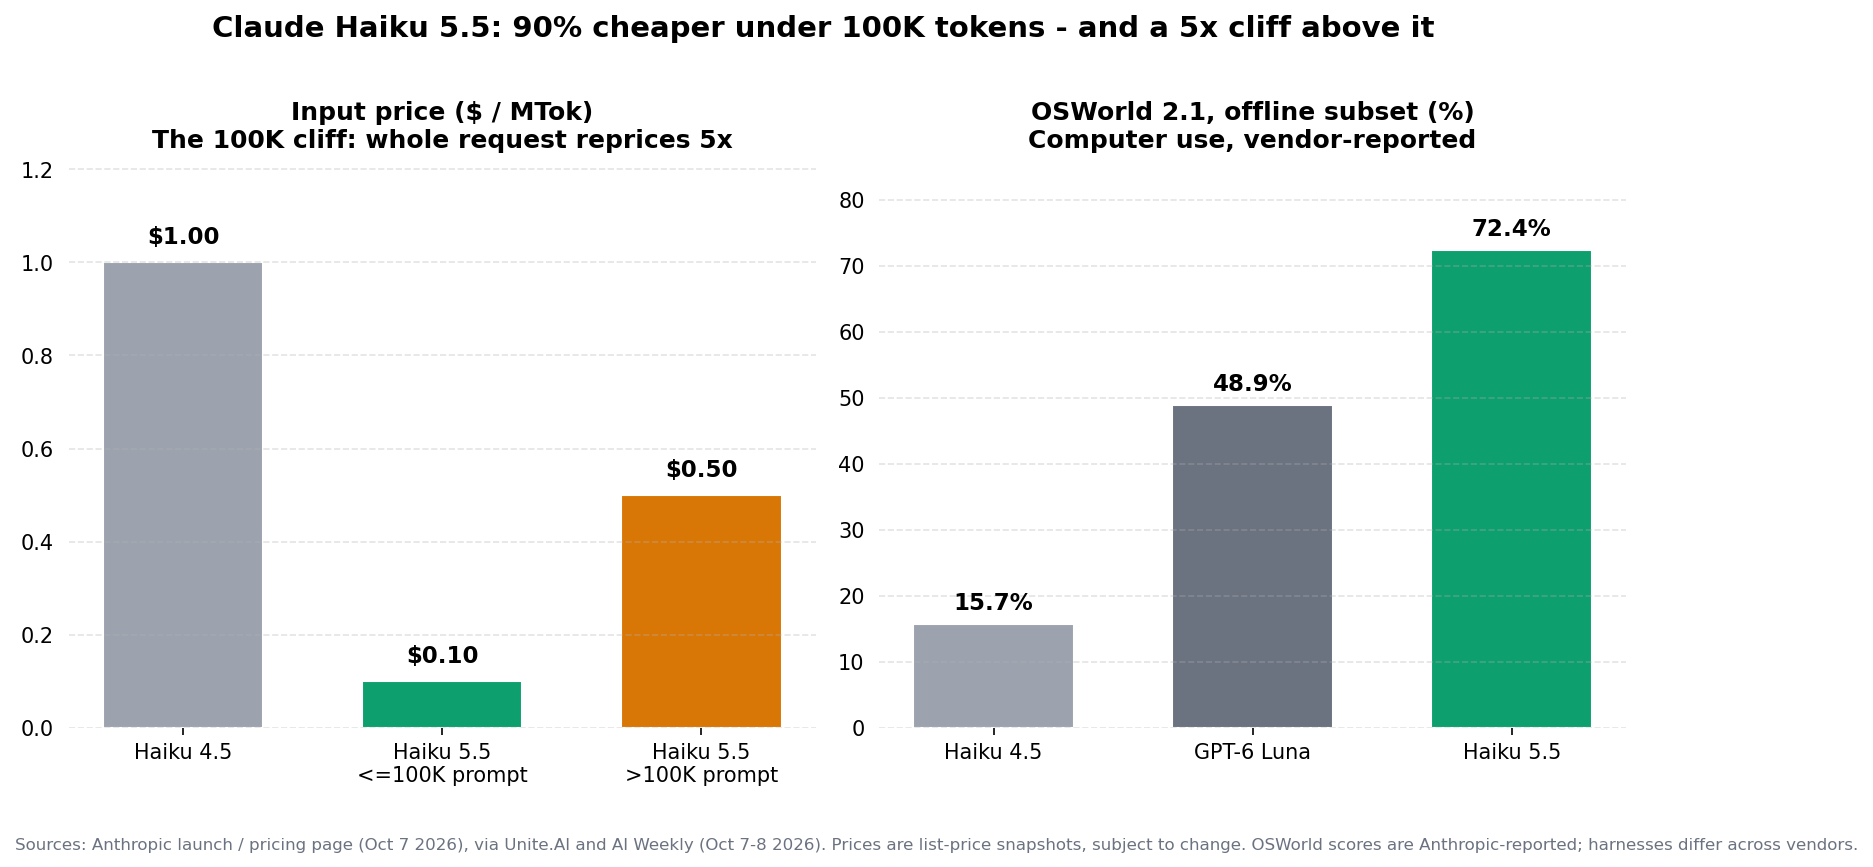
- OSWorld 2.1 (offline subset, computer use): 72.4%, up from Haiku 4.5’s 15.7% — and above GPT-6 Luna’s 48.9%.
- Humanity’s Last Exam: 45.9% without tools, 57.4% with tools, versus 10.2% / 18.7% for Haiku 4.5.
- Terminal-Bench 4.0 (agentic coding): 39.2%, where Haiku 4.5 scored 0.0%.
It is also the first Haiku with adjustable effort levels, and Anthropic positions it as a coding subagent alongside Sonnet 5.5 and Opus 5.5, plus summaries, extraction, classification, and live support. Vendor benchmarks, harnesses differ — but a 4.6x jump on OSWorld is not noise-level movement.
One weak result deserves a line, not a paragraph: Artificial Analysis reports 35% on AutomationBench-AA versus roughly 53–60% for GPT-6 Luna, Gemini 3.8 Flash, and GLM-5.3 Flash, and attributes part of it to a pre-release over-refusal issue Anthropic says it is fixing. Watch the re-run before trusting it for automation-heavy work.
The mechanism: a cliff, not a curve
For prompts up to 100,000 tokens, Haiku 5.5 lists at $0.10 input / $0.50 output per million tokens, with cache reads at $0.01. Haiku 4.5 was $1.00 / $5.00. That is a 90% list-price cut.
Above 100,000 tokens, every rate is 5x: $0.50 / $2.50, cache reads $0.05.
This is not a marginal bracket. The tier is chosen per request and applies to the whole request — output included. A 99,999-token prompt and a 100,001-token prompt are nearly identical workloads with a 5x price difference. Anthropic notes roughly 90% of Haiku 4.5 requests fell in the cheap tier, which is why the headline average saving is “only” ~75%.
Two more multipliers sit under the headline:
- A new tokenizer (shared with Sonnet 5.5 / Opus 5.5) counts roughly 30% more tokens for the same text than Haiku 4.5’s. Your token counts move even if your prompts don’t.
- Effort is now a cost dial. Artificial Analysis found Haiku 5.5 used roughly 162,000 output tokens per Intelligence Index task at maximum effort, about 3x GPT-6 Luna’s ~50,000. Same per-token price as Luna, very different per-task bill if you leave effort at max.
None of this cancels the launch. It changes what you measure: cost per completed task at a fixed effort level, with p95 prompt size — not list price per token.
Two side drops worth more than they look
- Sonnet 5.5 cache reads halved, $0.20 → $0.10 per MTok. Anthropic estimates ~20% cheaper Sonnet 5.5 on most agentic work, where cached context dominates.
- Monthly API credits roll out this week for paid plans: $100/month on Max 5x, $200 on Max 20x, up to $500 pooled on Team.
And a migration note from Anthropic’s own email: at Xhigh and Max effort, thinking cannot be turned off, manual thinking budgets are not supported, and API accounts created on or after August 31, 2026 must return thinking blocks unmodified within the same conversation. Budget a prompt-and-settings pass, not just a model-string swap.
What to do on Monday
Audit your top 3 high-volume calls:
- If p95 prompt size is under 90K tokens, trial Haiku 5.5 at low effort on the real workload and record cost per completed task.
- If p95 sits near 100K, split or compact the context first — crossing the cliff once erases the saving on that request.
- Compare against your current model at equal task success, not equal tokens.
The open question
Should small-model pricing have cliffs at all — or is a 5x step just a tax on sloppy context?
My lean: a cliff is defensible if it is this legible. 100K is a round, auditable threshold, and 90% of real traffic already lives under it. What I would not accept is discovering it on an invoice.
Sources
- Anthropic launch email, Oct 7 2026: pricing, effort levels, thinking and preserved-thinking migration notes, Sonnet 5.5 cache cut, Max / Team API credits.
- Reuters, Oct 7 2026, on the Haiku 5.5 launch and pricing tiers: https://www.reuters.com/business/anthropic-launches-third-claude-55-model-expanding-ai-lineup-before-planned-ipo-2026-10-07/
- Unite.AI, Oct 7 2026, pricing table, cache rates, Sonnet 5.5 comparison, benchmark table: https://www.unite.ai/anthropic-releases-claude-haiku-5-5-cutting-small-model-api-prices/
- Dev.to (importstatic), Oct 8 2026, on the 5x whole-request repricing at 100,001 tokens: http://dev.to/importstatic/claude-haiku-55-pricing-jumps-fivefold-at-100001-prompt-tokens-53ok
- Implicator.AI, Oct 8 2026, on Artificial Analysis token usage (~162K vs ~50K) and AutomationBench-AA (35%): https://www.implicator.ai/claude-haiku-5-5-matches-gpt-6-luna-pricing/
- AI Weekly, Oct 8 2026, launch summary: https://aiweekly.co/alerts/anthropic-cuts-claude-haiku-55-price-75-below-haiku-45
Share on
Twitter Facebook LinkedIn☕ Buy me a coffee! 💝
If you found this article helpful, consider buying me a coffee to support my work! 🚀